Prostir

Research-backed article

How to evaluate AI agents before launch

Evaluate AI agents before launch with real questions and clear acceptance cases. Check the answer, the sources and any action it takes; use the findings to refine the agent before wider use.

Before you read

What gets published

A launch scorecard that covers task success, groundedness, tool correctness, safety, cost, failure recovery, and human review.

Best for

Agent owners, product companies, and evaluators replacing demo-based confidence with repeatable release evidence.

Where the work happens

AI agent evaluation · Agent testing · Release gate · Microsoft.Extensions.AI.Evaluation

01

Evaluate the job, not the demo

Write the intended outcome, allowed tools, forbidden actions, evidence source, maximum cost and latency, approval points, and a stop condition before choosing a metric. A fluent answer can still accompany a wrong tool call or partial write.

Build cases from normal tasks, difficult edge cases, past failures, denied actions, stale or hostile content, tool timeouts, empty retrieval, and recovery. Keep every case tied to an exact product revision and expected behavior.

Use deterministic checks where the rule is exact and calibrated model-based evaluators where quality needs judgment. Human review remains necessary for ambiguous criteria, high-impact changes, and the launch decision.
02

A repeatable evaluation loop

  1. 01
    Create a bounded dataset

    Select representative evidence deliberately, remove secrets and unnecessary personal data, define expected outcomes, and keep a separate challenge set for abuse and recovery.

  2. 02
    Score answer and trajectory

    Check required and forbidden phrases, groundedness, completeness, task adherence, intent resolution, tool choice, arguments, side effects, retries, latency, and cost per successful job.

  3. 03
    Review, improve, and rerun

    Investigate failures, draft a bounded change, have a person accept or reject it, rerun the same cases, and compare against the prior product revision before publication.

03

Common false confidence

A few successful chats are examples, not a dataset. Average scores can hide one irreversible failure, so high-impact actions need exact denial and approval cases.

An LLM judge is not ground truth. Calibrate it against human labels, keep deterministic checks for exact rules, record failures as failures, and never turn model or billing errors into passes.

Evaluation is not security testing, production monitoring, or customer validation. Keep those evidence lanes separate even when they share cases, traces, or release thresholds.

04

Set the release decision

The useful output is not a colorful score; it is a decision rule the company can apply again after the next change.

  1. 01
    Name launch thresholds

    Set minimum task and tool accuracy, zero-tolerance cases, maximum cost and latency, acceptable variance, and the person authorized to approve residual risk.

  2. 02
    Run against an exact revision

    Record Agent, prompt, model, tools, knowledge, evaluator profile, cases, and seed or repetition policy so results remain comparable.

  3. 03
    Promote failures into regressions

    Add every material production or pilot failure to the retained suite, fix the owner, and require that case to pass before the next publication.

05

Evaluations in Prostir

Prostir has one implemented Evaluations module shared by Agent, Skill, and Company. It stores typed cases, evaluator profiles, bounded runs, results, failure signals, and improvement proposals under the exact product owner.

Evidence enters only after explicit selection and consent. Deterministic checks can run without a judge; judge-backed checks use Microsoft.Extensions.AI.Evaluation and require explicit model-credit authorization and a positive budget.

A run never mutates or publishes a product. A cited proposal stays pending until a person accepts it, and application rechecks the exact current draft revision before changing only that draft.

06

What if it gives the wrong answer or leaves a job unfinished?

AI can still misunderstand a request, use weak information or fail during an action. Give the Agent good sources and clear limits, then test examples that include mistakes. For a Flow, inspect the run and saved result rather than treating a confident reply as proof of completion.

A Prostir example

Ask a Store about a product for a particular delivery region. Its graph can connect products, delivery and returns facts; current price, stock and checkout still need confirmation from the commerce system.

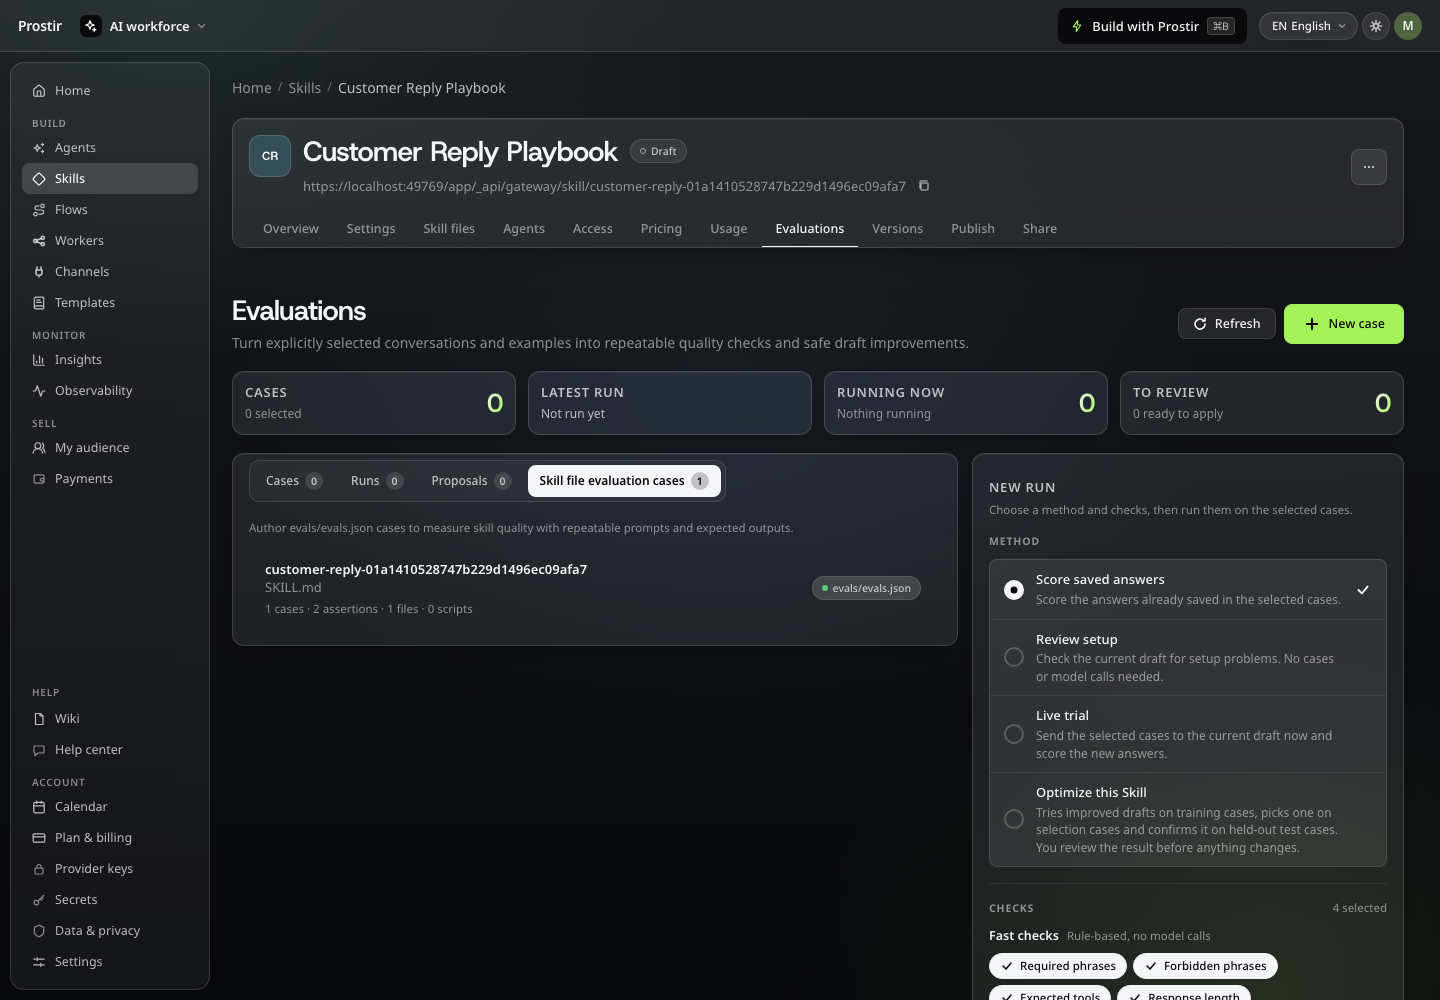
Review evaluation cases, then ask Builder to add a reusable reply checklist.

What to check first

Test an unavailable product, conflicting sources and an interrupted action. Check the actual saved result before treating the job as complete.

Skill evaluations workspace with its file-based evaluation view
Review the cases behind your method.

Solutions

AI agent builder for the way your business works

An agent with a clear job, your business context and a working path for the people who need it. You can test the agent with real requests, inspect its sources and allowed actions, and refine it in Builder before inviting others.

Solutions

Your next agent starts with your work.

Pick one customer question or routine task and build an agent for it with your own knowledge. Start your 7-day Creator trial, no card needed.

Image preview